The Open-Source Paradigm Shift
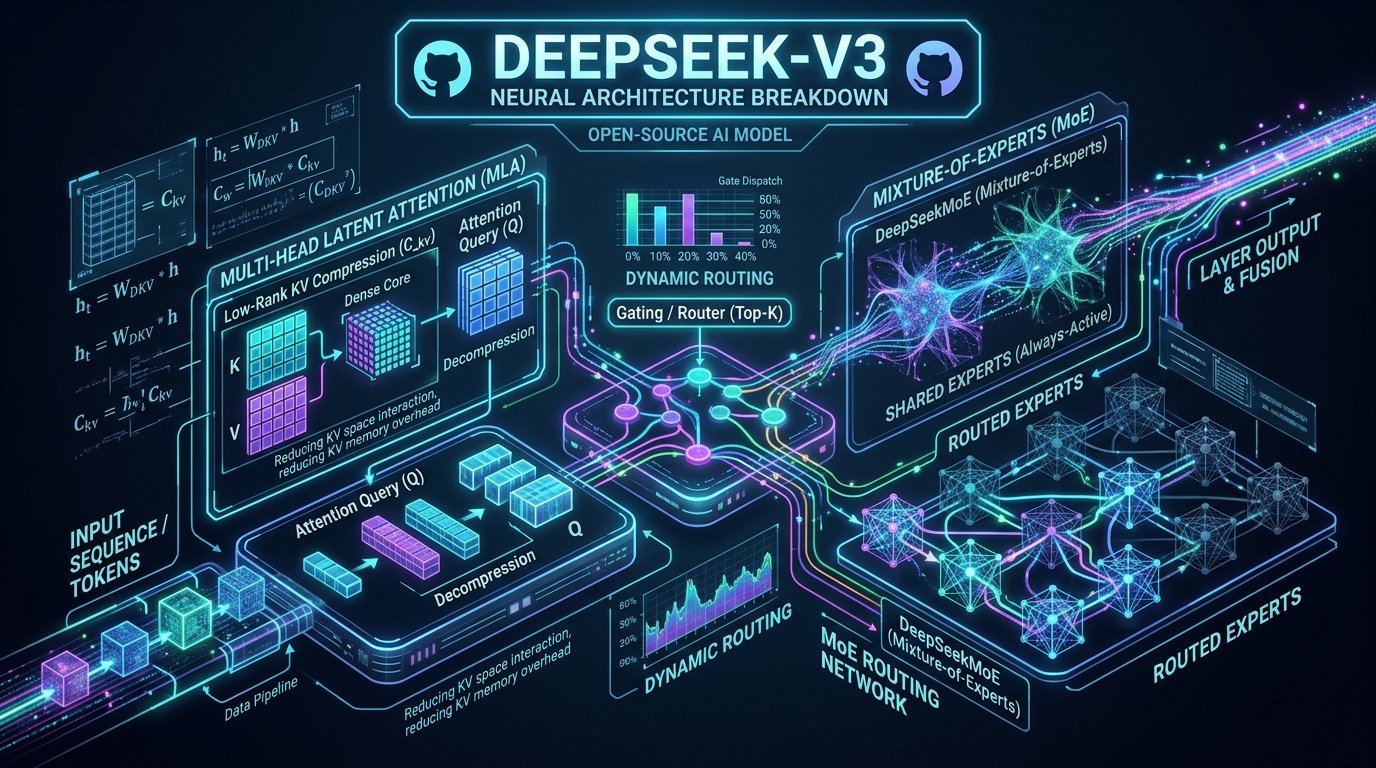
The release of DeepSeek-V3 demonstrated that high-performing frontier language models can be trained and served at a fraction of traditional hyperscaler budgets, fundamentally altering the economics of proprietary closed-source artificial intelligence.
Engineering Breakthroughs in DeepSeek-V3
The architecture introduces several foundational efficiency breakthroughs:
You May Also Like
- Multi-Head Latent Attention (MLA): Compresses key-value (KV) cache memory footprints by up to 90%, enabling massive serving concurrency on commercial GPUs.
- Sparse Mixture-of-Experts (MoE): Activates only 37 billion parameters out of 671 billion total per token, maximizing reasoning capacity without incurring latency penalties.
- Native FP8 Mixed-Precision Training: Overcomes numerical instability to accelerate matrix math across massive distributed GPU clusters.
- Multi-Token Prediction (MTP): Trains the model to predict multiple future tokens simultaneously, substantially improving generation throughput.
DeepSeek proves that algorithmic ingenuity and memory optimization can bridge the gap against multi-billion dollar supercomputing infrastructure.
Implications for Enterprise On-Premises Hosting
Enterprises can now deploy frontier-class reasoning models within their private cloud boundaries, ensuring strict regulatory compliance, data residency, and zero vendor lock-in.
Comments (0)
Leave a Comment